Site Reliability Engineer - Google Cloud Platform
Posted on: 13/11/2026
Job Description
Job Description :
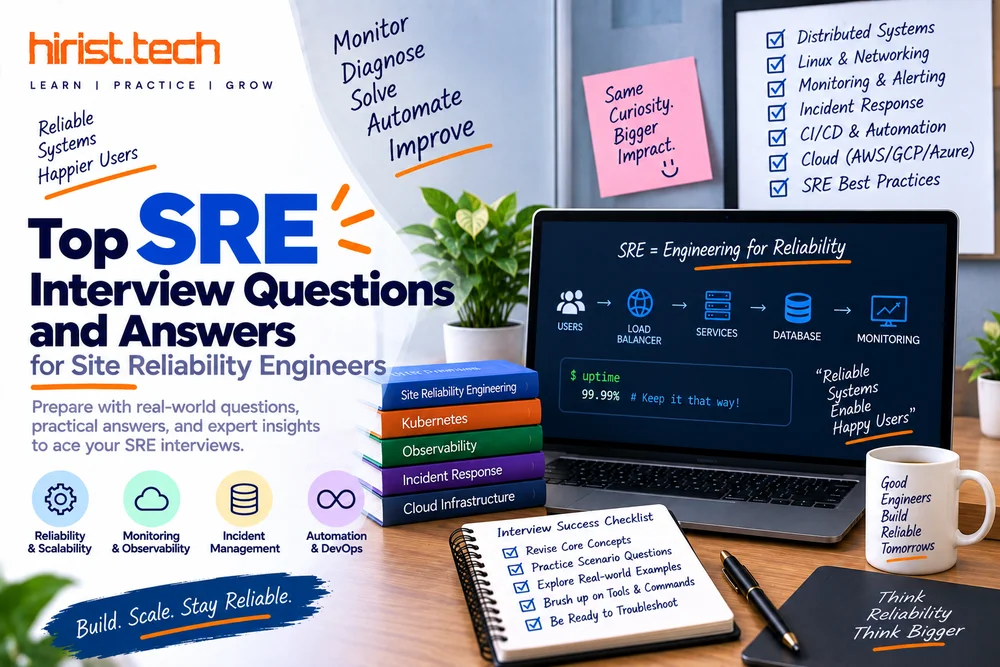
- Extensive knowledge of system administration on Linux environments, preferably working on high throughput and low latency systems.
- Strong hands-on experience with GCP services (or transferable AWS/Azure skills) networking, IAM, compute, storage, Kubernetes (GKE/EKS/AKS).
- Extensive knowledge of Docker and Kubernetes.
- Excellent understanding of distributed system design across process and site boundaries.
- Hands-on experience with service orchestration, management, deployment activities, configuration management and all necessary automation.
- Strong grasp of process isolation and containerization concepts, being able to apply them when necessary.
- Container orchestration: Deep understanding of Kubernetes deploying, scaling, monitoring clusters.
- Monitoring & Observability: Experience with tools like Prometheus, Grafana, Stackdriver, Datadog, New Relic, etc.
- Incident management: Practical experience responding to incidents, performing root cause analysis, and improving system reliability.
- Security best practices: Knowledge of cloud security, secrets management, and compliance basics.
- Good understanding of software development lifecycle, versioning, building, testing, staging and deployment processes with a strong continuous delivery mindset.

Did you find something suspicious?
Similar jobs that you might be interested in
Posted by
31
Posted in
DevOps / SRE
Functional Area
Site Reliability Engineering
Job Code
1683410